Retrieval-Augmented Generation
检索增强生成, 通常称为 RAG (Retrieval-Augmented Generation), 是一种强大的聊天机器人的设计模式. 其中, 检索系统实时获取与查询相关的经过验证的源 / 文档, 并将其输入生成模型 (例如 GPT-4) 以生成响应.
- 数据处理阶段:
- 对原始数据进行清洗和处理
- 将处理后的数据转化为检索模型可以使用的格式
- 将处理后的数据存储在对应的数据库中
- 检索阶段: 将用户的问题输入到检索系统中, 从数据库中检索相关信息
- 增强阶段: 对检索到的信息进行处理和增强, 以便生成模型可以更好地理解和使用
- 生成阶段: 将增强后的信息输入到生成模型中, 生成模型根据这些信息生成答案
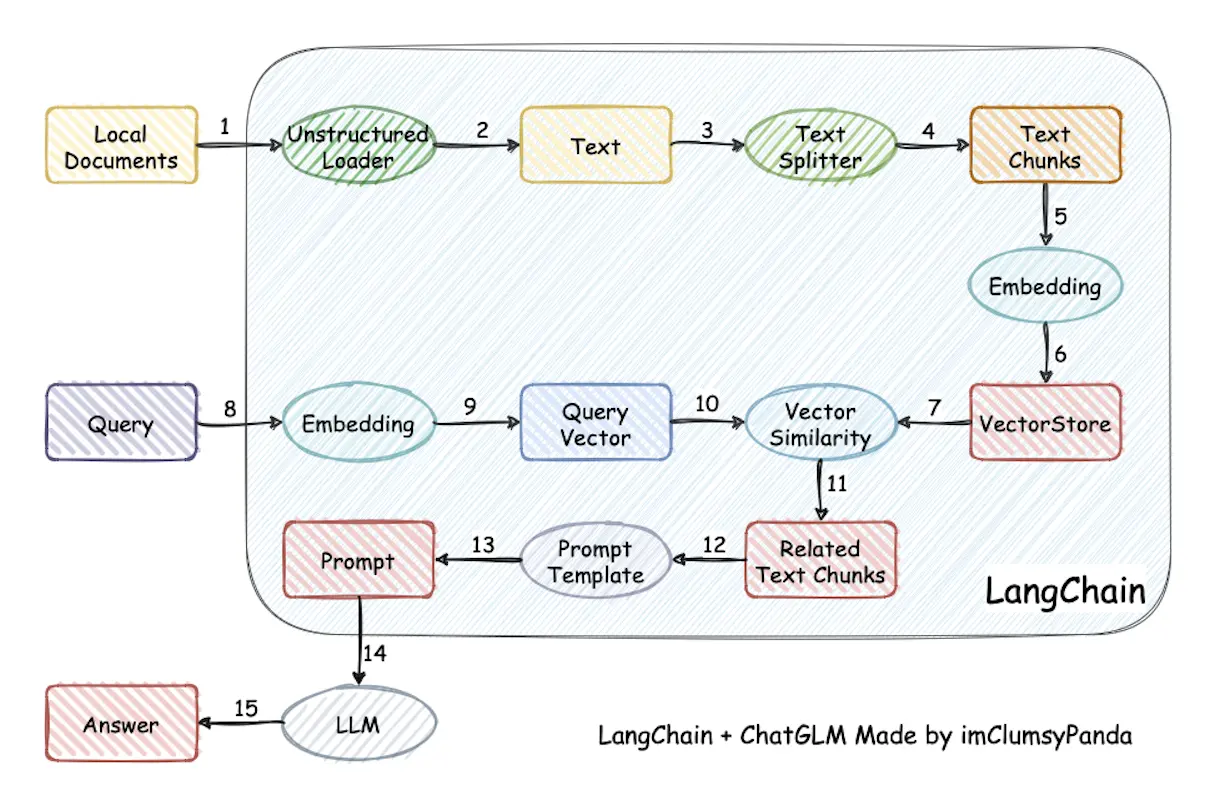
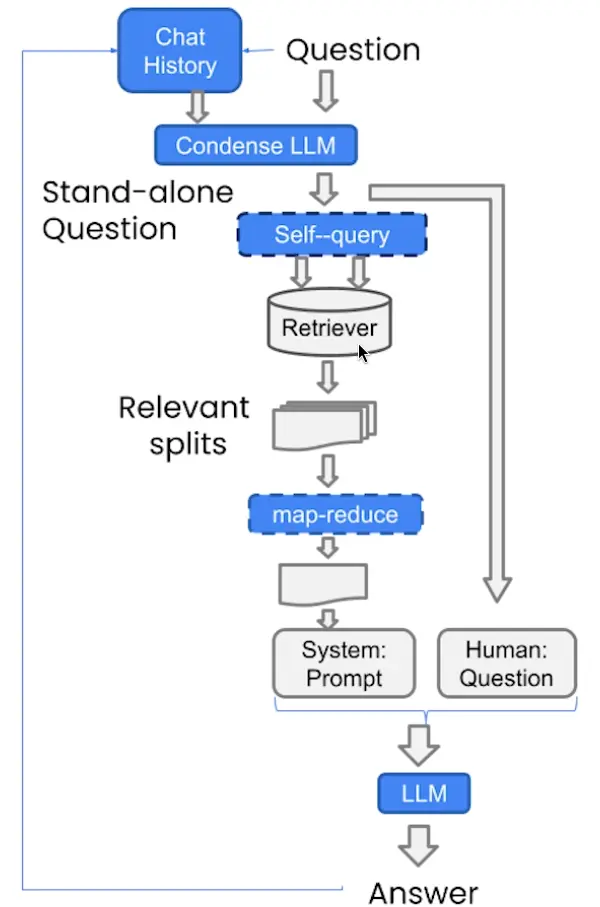
- Effect: reduce hallucination.
- Cost: avoid retraining.
Embeddings
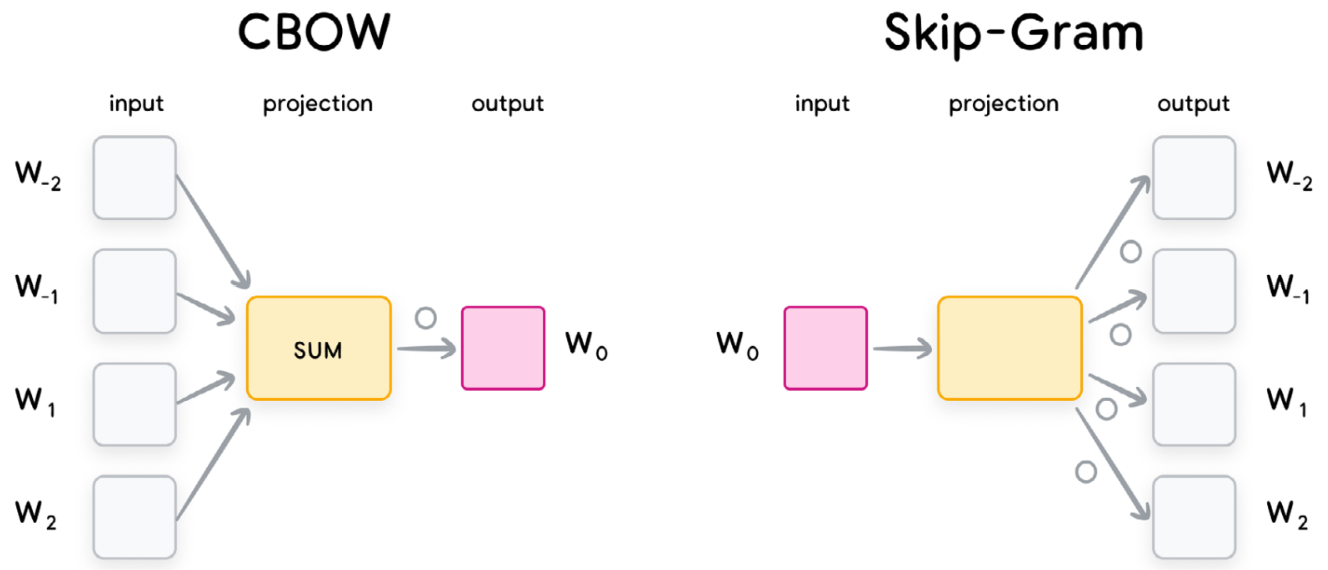
词嵌入是自然语言处理 (NLP) 中的一种技术, 将词汇映射到实数向量空间, 使得词汇之间的语义关系可以通过向量空间中的距离来表示.
- Continuous bag of words (
CBOW): Predict middle word, with embeddings of surrounding words as input. Fast to train and accurate for frequent words. - Skip-gram: predict surrounding words in certain range, with middle word as input. Slower to train but accurate for rare words.
GloVe/SWIVEL: Capture both global and local information about words with co-occurrence matrix.- Shallow
BoW. - Deeper pre-trained.
- Multimodal: image.
- Structured data.
- Graph.
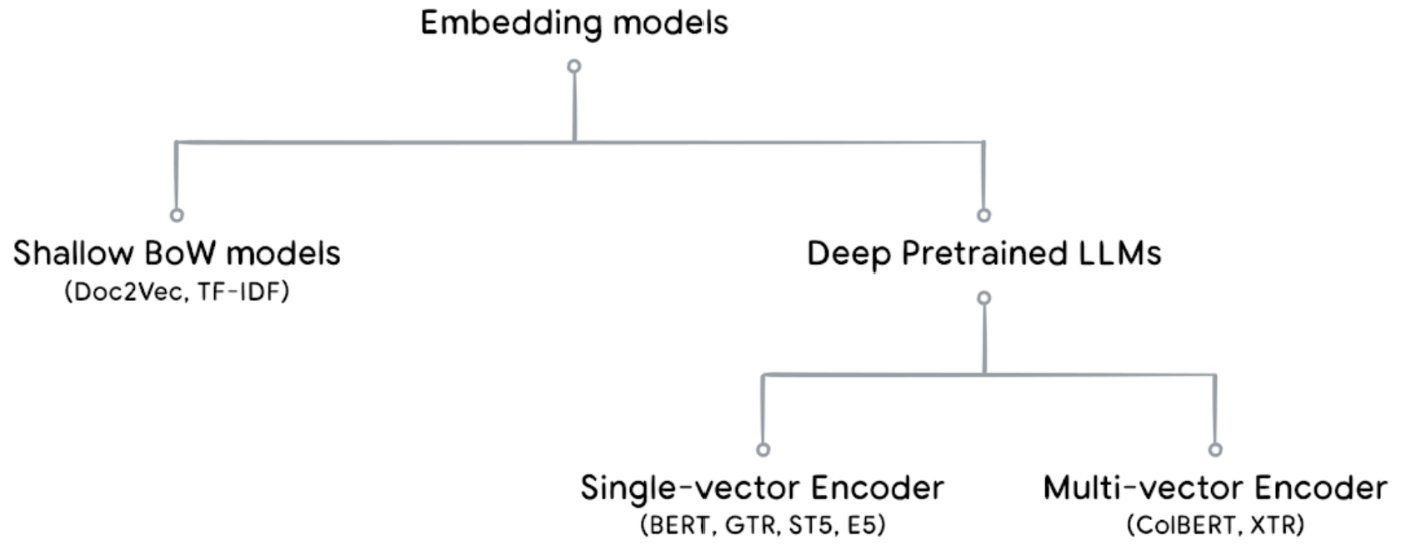
Maps two sets of data (user dataset, item/product/etc dataset) into the same embedding space.
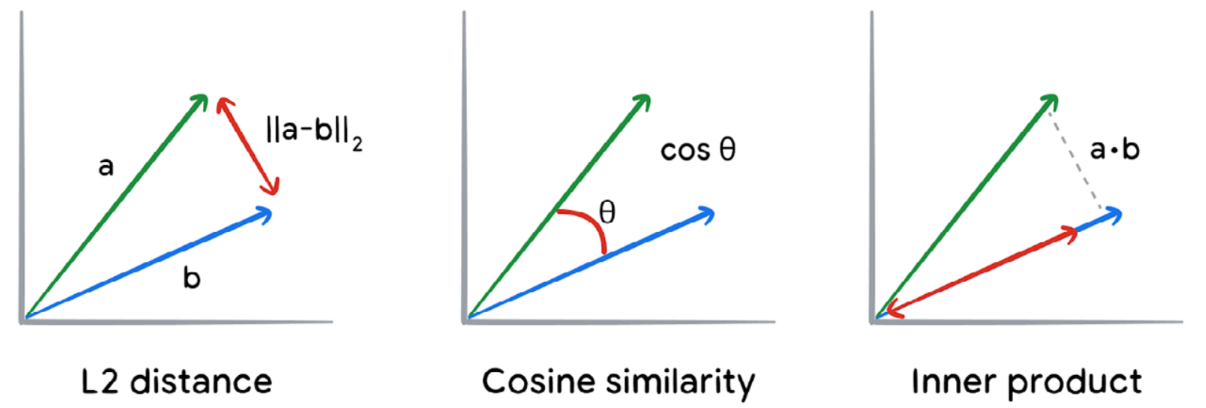
Embeddings + ANN (approximate nearest neighbor) vector stores
(ScaNN, FAISS, LSH, KD-Tree, and Ball-Tree):
- Retrieval augmented generation (RAG).
- Semantic text similarity.
- Few shot classification.
- Clustering.
- Recommendation systems.
- Anomaly detection.
Context
Context is everything when it comes to getting the most out of an AI tool. Improve the relevance and quality of the input, to improve the relevance and quality of a generative AI output.
Diversity
最大边际相关模型 (MMR, Maximal Marginal Relevance) 是实现多样性检索的常用算法:
它计算 fetch_k 个候选文档与查询的相关度,
并减去与已经选入结果集的文档的相似度,
这样更不相似的 k 个文档会有更高的得分.
Constraint
实现约束化检索:
- Metadata: 利用文档的元数据 (如时间戳、来源、类别等) 进行结构化约束.
- Self-Query: 根据用户输入的问题, 模型自身生成适合检索系统使用的查询 (query), 而不是提前人工设计关键词或标签.
Efficiency
- Prompt compression: 去除冗余文本
- RAG cache: 复用计算结果
Agentic
Agentic RAG (autonomous retrieval agents) actively refine their search based on iterative reasoning:
- Multi-query expansion (
MQE): 利用 LLM 生成语义等价的多样化查询 - Context-aware query expansion: 利用 LLM 生成与当前上下文相关的查询
- Hypothetical document embeddings (
HyDE): 利用 LLM 生成假设性的答案段落, 用假设段落去检索真实文档 - Multistep reasoning
- Adaptive source selection
- Validation and correction